
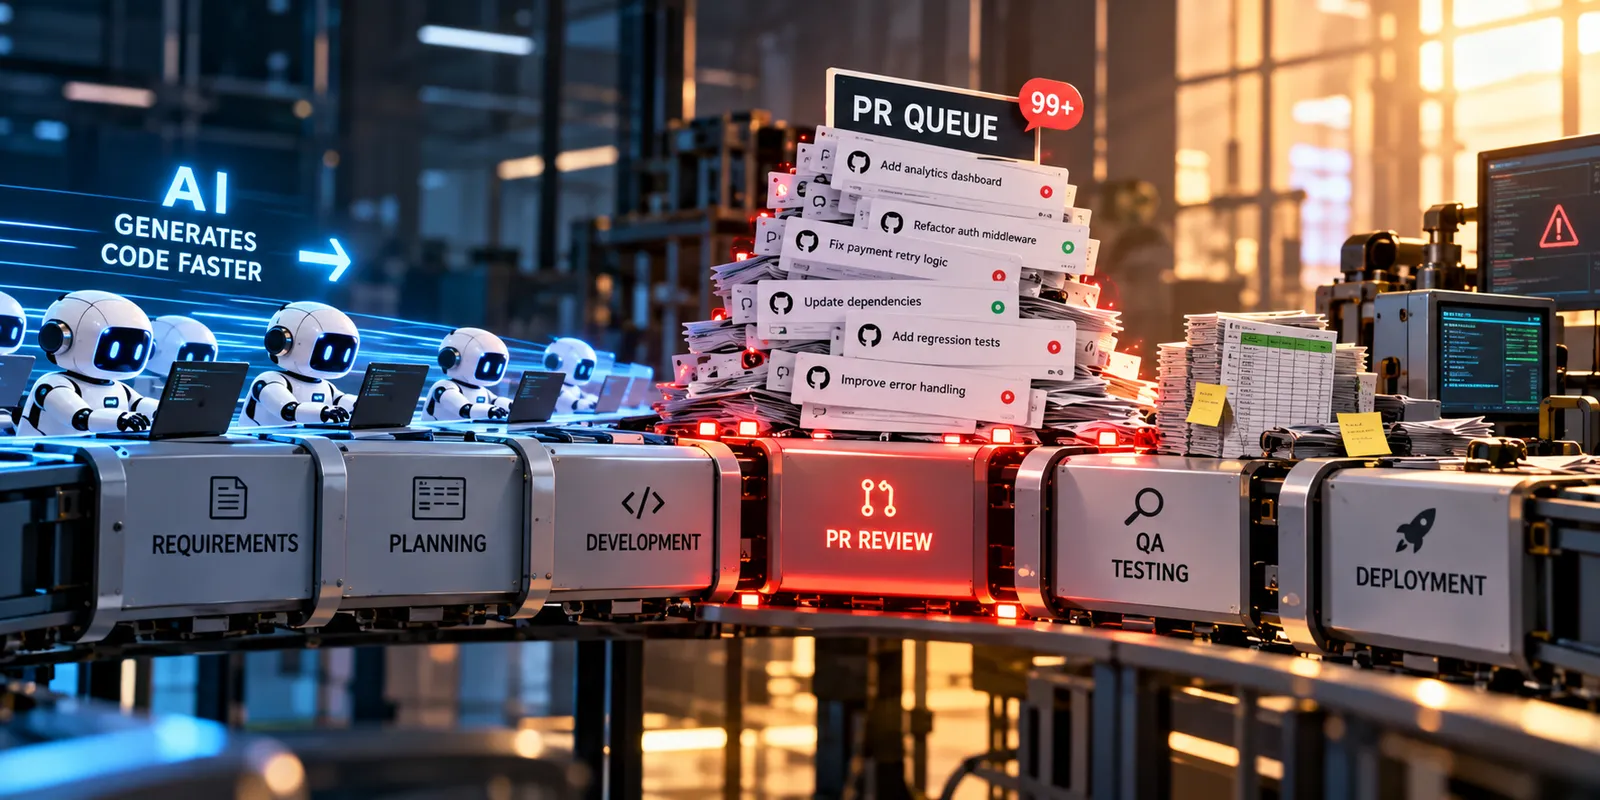


Every engineer has Claude Code. The Jira workflow is exactly what it was in 2020. Stories get pointed on Tuesday, the sprint closes every other Friday, a QA team clicks through a regression spreadsheet before each release, and the deploy still needs the one person who knows which step to run twice. PR queues are growing. Change failure rate is creeping up, quietly. Leadership is asking why the AI budget hasn’t shown up in the roadmap.
This is the most common operating model I see right now, and it is not a tooling problem. Putting agents inside a 2020 pipeline speeds up the one stage that used to be the constraint: writing code. Everything else in that pipeline (requirements, story breakdown, sprint commitment, a separate QA stage) was built to ration expensive engineering hours. Once code is cheap, the constraint moves to three places: how clearly intent is stated, how fast work can be verified, and how safely it can be deployed.
Here’s the uncomfortable part for most mid-market software companies. Those three things are exactly where a twenty-year-old platform is weakest. Intent lives in ticket fragments and in the heads of three long-tenured engineers. Verification is a manual QA team. Deployment has sharp edges nobody has had time to sand down.
So the question for a CTO or CPO isn’t “should we adopt AI-DLC or spec-driven development?” It’s “in what order do we fix the things AI just made into bottlenecks?” This post is my answer, grounded in what the data actually says and in what I’ve seen work on real legacy platforms.
Start with the most useful framing in the research. The 2025 DORA report (4,867 respondents) calls AI “an amplifier,” one that “magnifies the strengths of high-performing organizations and the dysfunctions of struggling ones.” Its key finding is that “AI adoption now improves software delivery throughput” but “still increases delivery instability,” and that “the greatest returns on AI investment come not from the tools themselves” but from “the quality of the internal platform, the clarity of workflows, and the alignment of teams.” Without that foundation, “AI creates localized pockets of productivity that are often lost to downstream chaos.”
That last line is the whole story, and the telemetry backs it up:
All of the telemetry above except DORA and the Microsoft study comes from vendors who sell into this problem. The direction is consistent across all of them anyway, and it matches what I see in portfolio companies.
One more caution before anyone builds a business case on developer sentiment. METR’s randomized trial of 16 experienced open-source developers found AI made them take 19% longer, while the developers believed afterward it had sped them up by 20%. METR’s February 2026 update says developers are “likely” more sped up now, but its new data is “an unreliable signal” because so many developers refused to work without AI. Returning developers showed an estimated 18% speedup with a confidence interval (-38% to +9%) that still crosses zero. The honest summary: individual gains are probably real and growing, self-reports are not measurement, and none of it matters if the system around the developer can’t absorb the output.
Most of the published playbooks come from companies that had the foundation first. Shopify, Stripe and Ramp built internal coding agents on top of mature CI, strong platform teams and deploy pipelines that were already fast. Shopify’s River now co-authors one in eight merged pull requests. Ramp’s Inspect writes roughly 30% of PRs merged to its frontend and backend repos. Stripe’s Minions produce “over a thousand pull requests merged each week”, all human-reviewed.
Those numbers are real, and they are downstream of a decade of platform investment. In a company with twenty years of code, the translation looks like this:
The AI-native assumptionYour realityWhat breaksVerification is automated and fastManual QA, a regression spreadsheet, dead test suitesEvery agent-written change waits for humans to click through itDeploys are small, frequent, reversibleRelease trains, a fragile deploy, a change freezeBatches get bigger, which is exactly what DORA says drives instabilityIntent is written down and agent-readableTribal knowledge, stale Confluence, ticket fragmentsAgents fill gaps with plausible assumptions at machine speedReview capacity scalesTwo senior engineers who understand the coreThey become the queue
This is why the order of operations matters more than the framework you pick. If you change the ceremonies first, you get faster generation into a system that still verifies at human speed. The queue grows and the change failure rate climbs quietly.
This is the order I’d run it in. Each step makes the next one safe.
You cannot manage a transition you can’t see, and METR’s perception gap shows that your team’s gut feel will be wrong in a flattering direction. Before touching process, instrument the five DORA metrics: change lead time, deployment frequency, change fail rate, failed deployment recovery time, and deployment rework rate. Add three that matter specifically for AI: PR pickup time, the share of PRs that are agent-authored, and model spend per merged change.
Two weeks of baseline data is enough. The point isn’t precision. It’s having a before picture so that six months from now you can tell the board whether the operating model changed or only the tools did.
What not to measure: lines of code, PR counts, or story points. Thoughtworks’ Technology Radar Volume 34 puts “coding throughput as a measure of productivity” in its Caution ring for good reason. Agents make throughput nearly free to inflate.
This is the step most organizations skip and the one that determines everything else. If verification is manual, every agent-written change waits on a human. Nothing downstream gets faster until this does.
Michael Feathers’ characterization testing is the right mental model for legacy code: “document your system’s actual behavior, not check for the behavior you wish your system had.” On a twenty-year-old platform you usually don’t know the correct behavior. You know the current behavior, and customers depend on it. Pin that down first.
This is also where agents are genuinely excellent, because the work is bounded and self-verifying. Earlier this year I built 1,500 regression tests across a fifty-repo legacy platform in three days, and the suite blocked a breaking release in its first week. The published cases point the same direction:
Your manual QA team is not the obstacle here. They are the most valuable input you have. Their regression spreadsheets and click-through scripts are the most accurate specification of what your system actually does that exists anywhere in the company. Turn them into automated tests. Playwright’s test agents ship a planner, generator and healer designed for exactly this: a Markdown test plan becomes Playwright test files, and the healer repairs failing tests. According to Katalon’s vendor survey, up to 82% of testers still use manual testing day to day, so you are not behind. You’re normal. But normal is now the bottleneck.
The QA role changes from executing tests to owning the harness: what gets asserted, which tests have teeth, what a release gate means. That is a promotion, and you should present it as one.
DORA’s guidance on working in small batches now says it directly: “AI adoption often leads to increased software delivery instability; working in small batches acts as a critical countermeasure to this risk.” Agents produce large changes by default. If your deploy process punishes frequent releases, work piles into big batches and you get DORA’s 2024 finding in your own incident log.
You don’t need to rebuild the pipeline. You need to remove the sharp edges on the path that carries the most change. Pick the one or two services with the highest commit traffic and get them to:
Agents can do much of this work themselves. Scripting the manual deploy steps, writing the runbook the one person carries in their head, and adding flags around risky code paths are all well-bounded tasks. Let them.
Only after verification and deploy safety are in place does it pay to make agents faster at writing code. The lever here is context, not model choice. DORA’s seven AI capabilities include “AI-accessible internal data” and “healthy data ecosystems” for a reason.
The minimum:
Keep these files short and human-maintained. Claude Code’s docs say bloated context files cause instructions to be ignored, and Thoughtworks’ Radar Vol. 34 puts “agent instruction bloat” in its Caution ring, noting that “hand-written versions are often more effective than LLM-generated ones.”
Be realistic about how far agents can go on your oldest code without people. Thoughtworks’ CodeConcise work cut legacy comprehension from six weeks to about two per module by pairing LLMs with a code knowledge graph. But their 2026 assessment of Claude Code on COBOL is blunt: agents alone can’t reliably ingest tens of millions of lines and draw a modernization roadmap, and every program still requires strong SME involvement. Your long-tenured engineers are the source of the map. Budget their time for it.
With more changes arriving, uniform review becomes the constraint. Every data source above says so. The fix is to stop treating all changes as equally dangerous. Here’s the tiering I recommend:
TierWhat’s in itReviewLowTest-only additions, docs, internal tooling, dev configAgent review plus green checks. Auto-merge is reasonable.StandardFeature work behind a flag in well-covered codeOne human reviewer, with an agent pre-review first so the human reads a summary and flagged lines, not a raw diffHighPayments, auth, data migrations, the legacy core, anything without characterization testsSenior human review, tests required before merge, and a spec for the change
Be precise about where auto-merge stops. The companies furthest along still keep humans on production code: Bessemer reports that Shopify “never merges code without a senior engineer’s review,” and its head of engineering, Farhan Thawar, adds that the required human reviewer “is now becoming a big bottleneck.” Stripe’s Minion PRs are human-reviewed too. Shopify does run review agents that often operate with no human in the loop, but those agents review. They don’t merge to production. The goal of tiering is to spend scarce senior attention on the high tier, not to remove it.
Also: keep agent-authored PRs small. LinearB found AI-assisted PRs run far larger than unassisted ones, and bigger PRs wait longer. A standing instruction in every context file to “one concern per PR” is the cheapest review-queue fix available.
This is where most transformations start, and it’s why most of them stall. Once verification, deployment and review can handle the volume, the 2020 ceremonies become the drag, and it’s time to change them.
Here’s the pragmatic caveat for legacy platforms: don’t adopt any of these frameworks wholesale. Birgitta Böckeler’s review of spec-driven tools found Kiro turned a small bug into four user stories and sixteen acceptance criteria (“like using a sledgehammer to crack a nut”) and concluded, “I’d rather review code than all these markdown files.” She also warns about a “false sense of control,” because agents still ignored instructions despite the templates. Thoughtworks’ Radar Vol. 34 says frameworks like Spec Kit “are better suited to greenfield projects than brownfield ones,” and prefers approaches built on “spec deltas rather than defining a complete specification upfront, making it well-suited for existing systems.”
That’s the right model for a twenty-year-old platform. You will never write a full spec of the existing system, and you shouldn’t try. Spec the change: what it must do, what must not break (point at the characterization tests), and the acceptance criteria. Use the heavy spec workflow for high-tier work and new modules. Skip it for small, well-covered fixes. Claude Code’s own guidance is a good rule of thumb: “If you could describe the diff in one sentence, skip the plan.”
Roles should follow the new workflow, not lead it. Reorganizing before the system can absorb the output just moves the queue.
Product. LinkedIn’s then-CPO Tomer Cohen announced in December 2025 that LinkedIn was replacing its APM program with an Associate Product Builder program. As he told Business Insider: “We’re going to teach them how to code, design, and PM at LinkedIn.” Andrew Ng wrote in April 2026 that some teams are pushing engineer-to-PM ratios “from, say, 8:1 to as low as 1:1.” The practical version for most companies: let PMs and designers build working prototypes, so that requirements arrive as running software rather than a document. That’s the highest-leverage change on the product side, and it costs nothing structurally.
But notice the counter-signal. At Anthropic, according to an interview with its head of platform engineering, teams still follow the two-pizza model of 5 to 8 engineers. The work changed instead: a team that ran one or two projects at a time “can now potentially run 4 or 5 projects in parallel,” and they’re finding they need more PMs, not fewer. When code is cheap, deciding what to build becomes the scarce skill. Don’t cut product capacity on the assumption that engineers will absorb it.
Engineering. Engineers shift from typing to orchestrating: decomposing work, running agents against well-specified tasks, and owning the outcome. That shift depends on steps 2 through 5 existing. An engineer can’t run three agents in parallel if each change waits a day for manual QA.
QA. As in step 2, the role moves from executing tests to building and owning the verification harness. This is the role change most likely to go badly if it’s handled as a cost cut rather than a skills shift, because these people hold the behavioral knowledge of the system.
Governance. Centralize the layer underneath and stay flexible on tools. Shopify routes all AI requests through one LLM proxy, tracks usage “by team, by project, by person,” and gets alerts “if someone spends more than $250 in tokens in a day.” They investigate those alerts rather than shut them down. They deliberately run multiple tools. A mid-market company doesn’t need to build that in-house, but it does need one place to see spend and one policy for which data agents can touch.
The transition fails when it’s owned by nobody or by everybody. Split it cleanly.
The CPO owns intent. Spec quality, acceptance criteria, prototypes as requirements, and the decision about what not to build. In a world where vague requirements get filled with assumptions in minutes, the quality of intent is the product organization’s main lever on engineering output. I’ve written before about why traceability from objectives to work matters more when teams move faster. It matters most here.
The CTO owns verification, deploy safety and governance. Steps 2 through 5 are engineering platform work. They are unglamorous, they don’t show up as features, and they’re the difference between AI as an amplifier of strength and AI as an amplifier of dysfunction.
Both own the metrics. Lead time, change fail rate, rework rate and review pickup time are shared numbers. If product is pushing more intent into the system than engineering can verify, it shows up there first.
If you’re a CEO or operating partner, ask two questions: what has happened to change fail rate and review wait time since AI adoption, and did team structure or roles change, or only the tools? A company that can’t answer the first is flying blind. A company whose answer to the second is “only the tools” is still running the 2020 model with a faster keyboard. In diligence, add: where do specs live and can agents read them, is review tiered by risk, what share of PRs are agent-authored and who owns them, and how does AI spend per engineer compare with the rest of the tooling budget.
If you’re a CTO, resist the urge to start with process. Start with the baseline, then the verification floor, then the deploy path. For a twenty-year-old platform, the regression suite and the one-command deploy are the AI strategy. Everything the published playbooks describe assumes they already exist.
If you’re a CPO, your organization’s output is now intent, and its quality sets the ceiling on what engineering can deliver. Get PMs building prototypes, move acceptance criteria to the front of the process, and hold onto product capacity. The evidence so far says you’ll need more judgment about what to build, not less.
The 2020 process wasn’t wrong. It was optimized for a world where engineering hours were the scarcest resource in the building. They aren’t anymore. The scarce resources now are clear intent, fast verification and safe deployment, and on a legacy platform you have to build those before you can use the speed you’ve already paid for.
Research and benchmarks: DORA 2025 State of AI-assisted Software Development · DORA 2024 Accelerate State of DevOps · DORA metrics · DORA: Working in small batches · DORA: Trunk-based development · DORA: Continuous delivery · METR: Early-2025 AI and experienced OSS developer productivity · METR: Changing our developer productivity experiment design (Feb 2026) · Murphy-Hill et al.: Microsoft’s early-2026 rollout of command-line coding agents · Nikolov et al.: How is Google using AI for internal code migrations?
Vendor telemetry and surveys: Faros AI: The AI Productivity Paradox (2025) · Faros AI: Acceleration Whiplash (2026) · LinearB 2026 Software Engineering Benchmarks · LinearB: 8 million PRs · Opsera 2026 AI Coding Impact Benchmark · Qodo 2026 State of AI Code Quality · Katalon: Test automation statistics
Company practice: Bessemer Atlas: Inside Shopify’s AI-first engineering playbook · Shopify Engineering: Under the River · Ramp: Why we built our own background agent · Stripe: Minions · Airbnb: Accelerating large-scale test migration with LLMs · Andy Jassy on Amazon Q Java upgrades · Lenny’s Podcast: Why LinkedIn is replacing PMs · Engineering Leadership: How Anthropic builds AI-native engineering teams · Andrew Ng: AI-native software development needs generalists
Methods and tooling: AWS: AI-Driven Development Life Cycle · awslabs/aidlc-workflows · GitHub Spec Kit · Kiro specs · Böckeler: Understanding spec-driven development · Thoughtworks Technology Radar · Thoughtworks: Legacy modernization meets GenAI · Thoughtworks: Claude Code and COBOL modernization · Feathers: Characterization testing · Fowler: Strangler Fig Application · Playwright test agents · Claude Code memory docs · Claude Code best practices · AGENTS.md · Linux Foundation: Agentic AI Foundation


